
上一篇我們從正面、負面句子的 activation difference 中建立 steering vector,再把它加入新的 forward pass,改變模型的情緒或拒答傾向。這類 direction 通常表示某種 property:
positive ↔ negative
helpful ↔ unhelpful
refuse ↔ comply
但大型語言模型能做的不只是表現出某種性質。它還能從 context 中學會一個任務。例如我們給模型幾組 demonstrations:
hot → cold
up → down
open → close
happy →
即使沒有明確說出規則,模型也可能推斷「這個任務是在產生 antonym」這就是 In-Context Learning(ICL):模型不需要更新 weights,只靠 prompt 中的 examples,就能暫時學會一個 input-output mapping。但這帶來一個很有趣的問題:
模型讀完這些 demonstrations 後,會不會把「現在要執行的任務」壓縮成某個內部 vector?
如果真的存在這樣的 vector,我們或許可以把它從 few-shot prompt 中抽出來,再放進一個完全沒有 demonstrations 的 prompt,直接讓模型執行同一項任務。這就是 Function Vector 與 Task Vector 背後的核心想法。
先回想上一篇的 sentiment steering。我們從:
positive examples − negative examples
建立一條 direction,然後把模型往 positive 或 negative 的方向推。它比較像在控制模型現在處於什麼狀態,或表現出什麼性質。Function Vector 想捕捉的則是模型現在應該執行哪一種 input-output function。
例如:
word → antonym
country → capital
English word → French translation
singular noun → plural noun
present tense → past tense
這裡重要的不是某個單一 concept,而是一個操作規則。
這個界線不是絕對的。Property、behavior、task 和 function 在高維 representation 中可能彼此重疊;不同研究使用的名稱也不完全一致。但這個區分可以先幫我們抓住直覺:Steering vector 常用來改變模型「怎麼表現」;Function Vector 則試圖改變模型「正在做什麼」。
Todd 等人在 2024 年的研究中,分析大型語言模型如何處理具有 demonstrations 的 ICL prompts。[1] 例如:
hot → cold
big → small
early → late
happy →
模型必須先從前面的 examples 推斷任務是:
input → antonym
接著才能對新的 query 產生 sad。研究者首先問:模型中的哪些 Attention Heads,對辨識並執行這項任務特別重要?他們會先收集大量同一任務的 few-shot prompts,記錄不同 Attention Heads 在 query position 的 activation。接著把 prompt 中的 labels 打亂:
hot → late
big → cold
early → small
happy →
現在 examples 的 input-output mapping 已經被破壞,模型很難正確推斷任務。研究者再把正常 demonstrations 中某個 head 的平均 activation,patch 進這些 shuffled-label prompts,觀察正確任務表現是否被恢復。如果 patch 某個 head 能明顯救回 performance,就表示這個 head 的 activation 可能正在傳遞 task-related information。這其實就是前面介紹過的 causal intervention。不是只看哪個 head 和 task 有 correlation,而是真的把 activation 換進去,測試它能不能改變行為。
要注意,這一步還不是在建立某個特定任務的 Function Vector,而是在找出一組跨不同 ICL tasks 都具有較高 causal effect 的 Attention Heads。找到這些 heads 之後,我們才會針對 Antonym、Capital 等不同 task,分別抽取它們的 task-conditioned activation,組成各自的 Function Vector。
研究者先利用 causal mediation analysis,找出少數對多種 ICL tasks 具有較高 causal effect 的 Attention Heads。接著,他們把這些 heads 在某項任務上的平均 task-conditioned activation 取出,經過各自的 output projection,再加總成一個 vector:
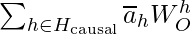
其中:
這裡為了把 Attention Head 本身的 activation 與寫入 Residual Stream 的 contribution 分開來看,我們用 a_h 表示 W_O 投影前的 head activation;經過 W_O^h 後,才得到 d_model 維的 residual-stream contribution。需要注意的是,Todd et al. 原文的 notation 會直接把經過 output projection、已經寫入 Residual Stream 的 head output 記為 a_{lj}。這裡則刻意把 projection 前的 head activation 與 W_O 分開寫,方便看清楚 Function Vector 是如何從 individual heads 的 activation 組成的;兩種寫法描述的是同一個運算。
直覺上就是:
找出負責攜帶 task information 的 heads
↓
收集它們在同一任務中的典型 activation
↓
轉換成寫入 Residual Stream 的 contributions
↓
把它們加總成一個 Function Vector
更具體來說,我們會準備許多屬於同一 task 的 ICL prompts,分別跑過模型。在每個 prompt 的 query position,取出指定 causal head 在 output projection 前的 activation,然後跨 prompts 做平均,得到這個 head 對該 task 的典型 activation。接著,再經過該 head 的 W_O 投影到 residual-stream space。最後把不同 causal heads 的 contributions 加總,就得到一條 d_model 維的 Function Vector。
many Antonym ICL prompts
        ↓
causal head h 的 query-position activation
        ↓ average
mean task-conditioned head activation
        ↓ W_O
residual-stream contribution
        ↓ sum over causal heads
Antonym Function Vector
研究中發現,具有較高 causal effect 的 heads 往往集中在模型的中間 layers,而且這些 heads 會強烈 attend 到 demonstrations 中的 output tokens。[1]
可以把它想成:
每個 demonstration 都在 context 中留下一點「這項任務要怎麼做」的線索,而一小群 Attention Heads 負責把這些線索收集、傳遞到 query position。
找到 Function Vector 之後,真正關鍵的實驗是:
如果 prompt 裡完全沒有 demonstrations,只把 vector 加進模型,它還能不能執行任務?
例如,模型原本看到:
When I think of sit, I usually think of
可能會接:
a chair
但把 Antonym Function Vector 加進模型中間 layer 後,模型可能改成:
stand
同樣地,加入 country-to-capital Function Vector 後:
When you think of Egypt,
模型會更傾向接:
Cairo
即使這些 prompts 的形式和原本用來抽取 Function Vector 的 few-shot examples 完全不同,vector 仍然能在一定程度上觸發相同的 task。[1] 這個結果很重要。因為它表示 Function Vector 不只是記住某一組 demonstrations 的表面格式。它可能捕捉了某種更抽象、可以被轉移到新 context 的 input-output function。
今天的 companion notebook 會參考原始研究釋出的 code,先選擇一個模型能穩定完成的簡單任務,例如:
Antonym
Country → Capital
Singular → Plural
Present → Past
這邊只需要先注意到最核心的兩步。第一步,從多組 demonstrations 中建立 Function Vector:
完整重現原論文時,前面還需要先用 shuffled-label prompts 做 causal mediation analysis,替每個 Attention Head 計算 causal effect,再挑出 effect 最大的一小群 heads。為了讓今天的實作聚焦在 Function Vector 本身怎麼被抽取與使用,我們會直接使用前一步已經選出的 selected_heads。
接著,程式會讓多組 Antonym demonstrations 跑過模型,收集這些 causal heads 的 task-conditioned activation,跨 prompts 平均後再合併成 Function Vector
function_vector = extract_function_vector(
    model=model,
    task_examples=antonym_examples,
    causal_heads=selected_heads,
)
如果把 extract_function_vector() 拆開來看,它做的事情大致是:
for each ICL prompt:
    forward pass
    ↓
    取 causal heads 在 query position 的 activation

across prompts:
    ↓
    對每個 head 做平均

for each causal head:
    ↓
    轉成寫入 residual stream 的 contribution

最後:
    ↓
    將所有 causal-head contributions 加總
    ↓
    Function Vector
所以 Function Vector 並不是「把整個 hidden state 隨便平均」,而是先透過 causal intervention 找到重要的 Attention Heads,再抽取這些 heads 在特定 task 下的 activation,跨 prompts 做平均,最後合併成 Function Vector。
接著,把 vector 加入一個沒有 demonstrations 的 prompt:
baseline = generate(
    model,
    prompt="The opposite of happy is"
)

intervened = generate_with_vector(
    model,
    prompt="The opposite of happy is",
    vector=function_vector,
    layer=intervention_layer,
)
generate_with_vector() 則會在指定的中間 layer,將這條 d_model 維 Function Vector 加到目前 prediction position,也就是序列最後一個 token 的 residual stream,再讓後面的 layers 繼續計算。因此,模型收到的 prompt 本身可以完全沒有 demonstrations,但內部 activation 已經被加入代表該 function 的 signal。若要生成多個 tokens,也可以在後續 autoregressive generation 的每一步,持續把同一條 Function Vector 加到最新 token position。
Zero-shot prompt
      ↓
early layers
      ↓
last-token residual:
h_l + Function Vector
      ↓
remaining layers
      ↓
task-consistent output
然後比較:
Baseline output
vs.
Function-vector output
幾乎同一時間,Hendel、Geva 與 Globerson 從另一個角度研究相似的問題。[2] 他們提出一個非常直覺的 ICL 模型:
Demonstrations
↓
模型推斷 task
↓
形成 Task Vector
↓
Task Vector + New Query
↓
Output
也就是把 few-shot demonstrations 看成一組臨時 training data。模型讀完 examples 後,將它們壓縮成一個 Task Vector,再利用這個 vector 處理新的 query。研究者會從正常 few-shot prompt 的某個 hidden state 中抽取 task-related representation,再把它 patch 到沒有 demonstrations 的 dummy prompt。如果 patch 之後,zero-shot prompt 的 task performance 明顯恢復,就表示這個 hidden state 可能攜帶了足以調節模型執行該 task 的資訊。
他們在多種 tasks 與 models 上發現,ICL 的效果在不少情況下確實可以被一個 compact task representation 部分重現。[2]
它們非常相關,但不是完全相同的方法。
| 方法 | 核心做法 |
|---|---|
| Function Vector | 找出具有 causal effect 的 Attention Heads,再合併它們的 task-conditioned contributions |
| Task Vector | 從 few-shot prompt 的 hidden state 中抽取對 task 的 compact representation |
| Activation Steering | 從 contrastive examples 建立 direction,直接控制某種 property 或 behavior |
三者都在操作 activation-space representations。
但它們的研究問題稍有不同:
這些名稱在文獻中也不是完全統一的。此外,Task Vector 有時也被用來表示 fine-tuning 前後的 weight difference;那是另一條 weight-space task arithmetic 文獻,和這裡的 activation-space ICL Task Vector 不同。
如果把前面幾天放在一起看,我們其實已經走過一套完整的流程:
讀取 representation
↓
找出和 concept / task 有關的 direction
↓
利用 intervention 驗證 causal effect
↓
再用同一個 representation 控制模型
這類以高階 representation 為分析與介入單位的方法,常被統稱為 Representation Engineering(RepE)。[3]
RepE 把工作分成兩大部分:
相較於從 individual neurons 或完整 circuits 往上拼,RepE 採取的是較 top-down 的視角:
先從我們關心的高階現象出發,再尋找能夠讀取與控制它的 population-level representation。
這種方法不一定能提供完整的 mechanistic explanation。但在 monitoring、auditing 與 model control 上,它往往比完整 reverse-engineering 一個 circuit 更容易快速使用。[3]
Function Vector 和 Task Vector 的結果很吸引人。但我們不能把它們理解成每個 task 在模型裡都有一條固定、完整、唯一的 vector。幾個需要注意的問題包括:
後續研究也顯示,單一 global task vector 並不是所有 ICL tasks 的完整描述;在一些 categorization tasks 中,task information 可能仍分散在不同 demonstrations 的局部 hidden states,單純把它們平均成一個 vector 反而會遺失資訊。[4] 因此,Function Vector 比較適合被理解成一個 compact、具有 causal effect、能部分觸發 task behavior 的內部 representation。而不是整個 task mechanism 的完整原始碼。
過去兩天,我們一直使用一個非常方便的假設:某種 behavior 或 function,可以用一條 direction 近似。這個假設讓 probing、steering 與 Function Vector 都變得非常簡單。但像:
這些複雜 phenomena,真的都只需要一條直線嗎?還是它們其實存在於一個多維 subspace,甚至需要更複雜的幾何結構?下一篇,我們會從單一 direction 往前一步,介紹 Conceptors 與 Concept Subspaces。
[1] Todd, E., Li, M. L., Sharma, A. S., Mueller, A., Wallace, B. C., & Bau, D., “Function Vectors in Large Language Models”, International Conference on Learning Representations (ICLR), 2024. https://arxiv.org/abs/2310.15213
[2] Hendel, R., Geva, M., & Globerson, A., “In-Context Learning Creates Task Vectors”, Findings of EMNLP, 2023. https://aclanthology.org/2023.findings-emnlp.624/
[3] Zou, A., Phan, L., Chen, S., et al., “Representation Engineering: A Top-Down Approach to AI Transparency”, 2025 revision. https://arxiv.org/abs/2310.01405
[4] Zheng, B., et al., “Label Words as Local Task Vectors in In-Context Learning”, 2025 revision. https://arxiv.org/abs/2406.16007


 iThome鐵人賽
 看影片追技術